Shangzhe Di(狄尚哲)
PhD Candidate at SJTU · Student Researcher at Google DeepMind
shangzhe.di@gmail.com / CV / Google Scholar / GitHub
Hi, I am a fourth-year PhD candidate at Shanghai Jiao Tong University, advised by Prof. Weidi Xie. My research focuses on video understanding, multi-task visual representation learning, and world models.
I am currently a Student Researcher at Google DeepMind in London, working on agentic 4D world modeling. Previously, I interned at ByteDance Seed and Alibaba.
I'm graduating in 2027 and open to industry opportunities. Feel free to reach out if you think there's a good fit.
Experience
Education
Publications * equal contribution
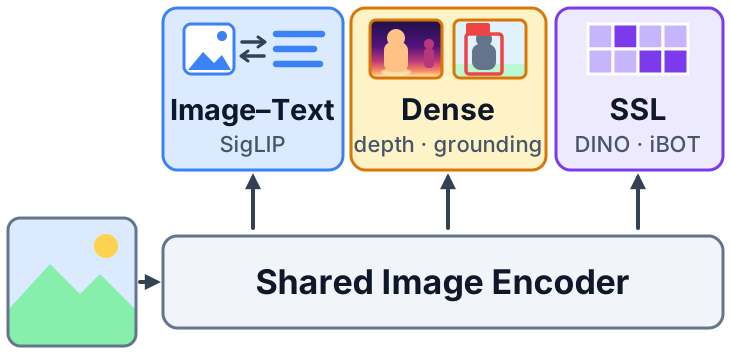
Multi-task pre-training can yield scalable general-purpose visual representations.
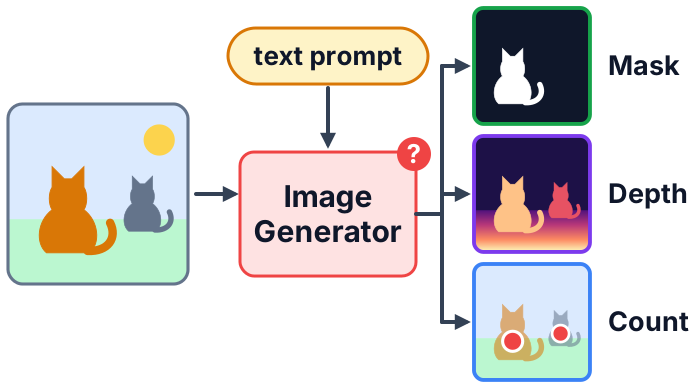
Image generators exhibit strong zero-shot perception capabilities through text prompting.
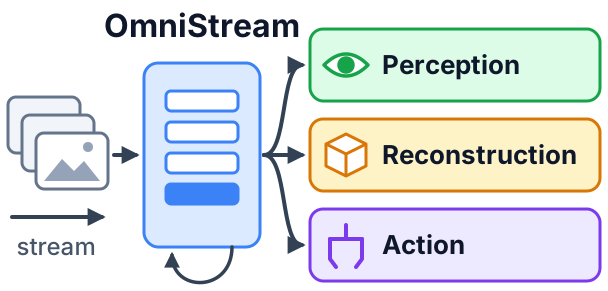
A unified streaming visual backbone for perception, reconstruction, and action.
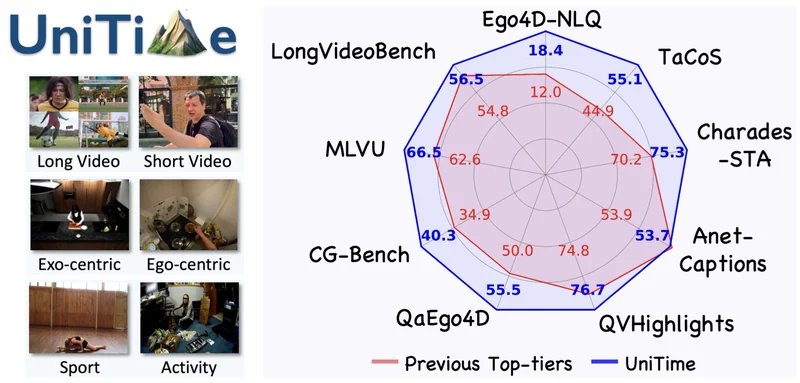
Towards universal video grounding with superior accuracy, generalizability, and robustness.
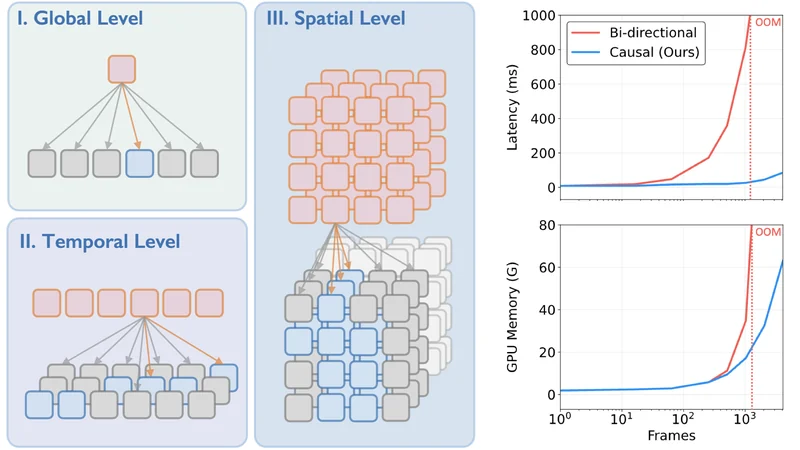
Streaming video representations at global, temporal and spatial granularity, learned via multi-task training.
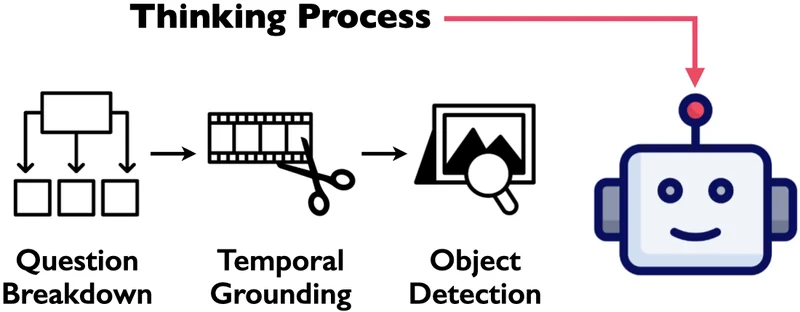
Distill multi-step reasoning and spatial-temporal understanding into a generative Video-LLM.
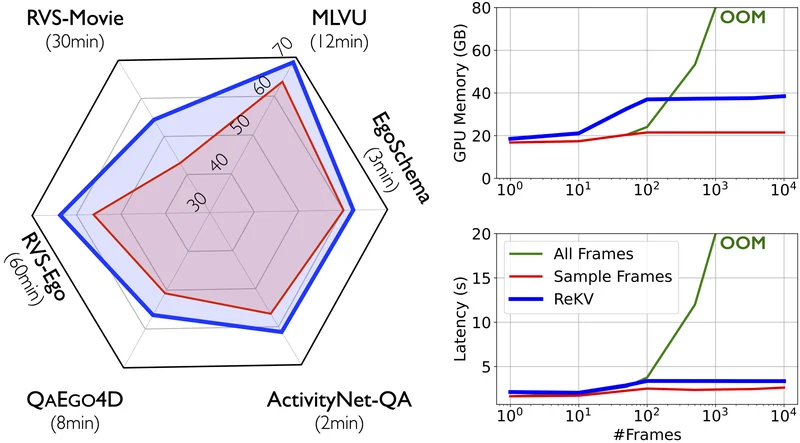
A training-free approach enabling Video-LLMs for streaming video question-answering.
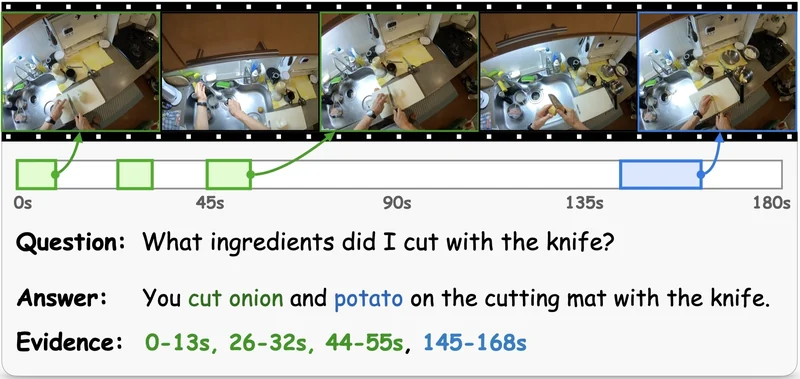
Pinpoint scattered visual evidence in long egocentric videos while responding to questions.
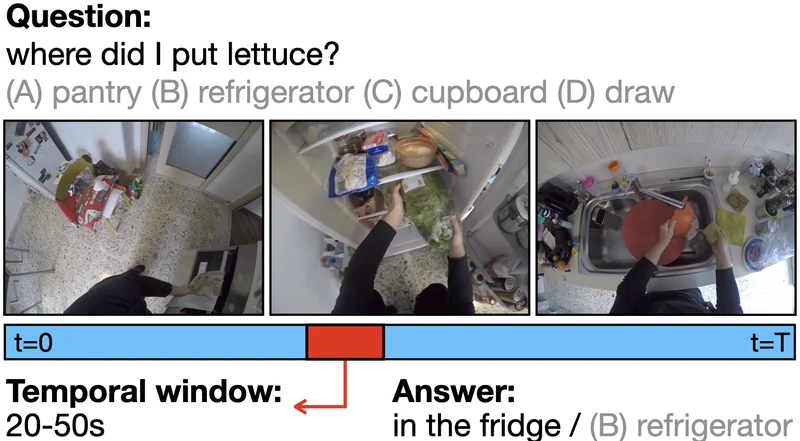
Simultaneous query grounding and answering in long, egocentric videos.
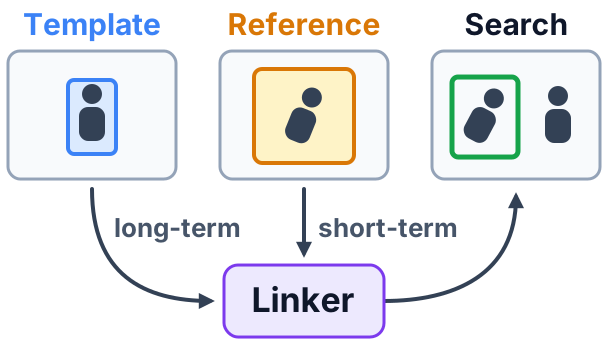
Associate the initial template with a fast-updated reference region for robust visual tracking.
Honors & Awards
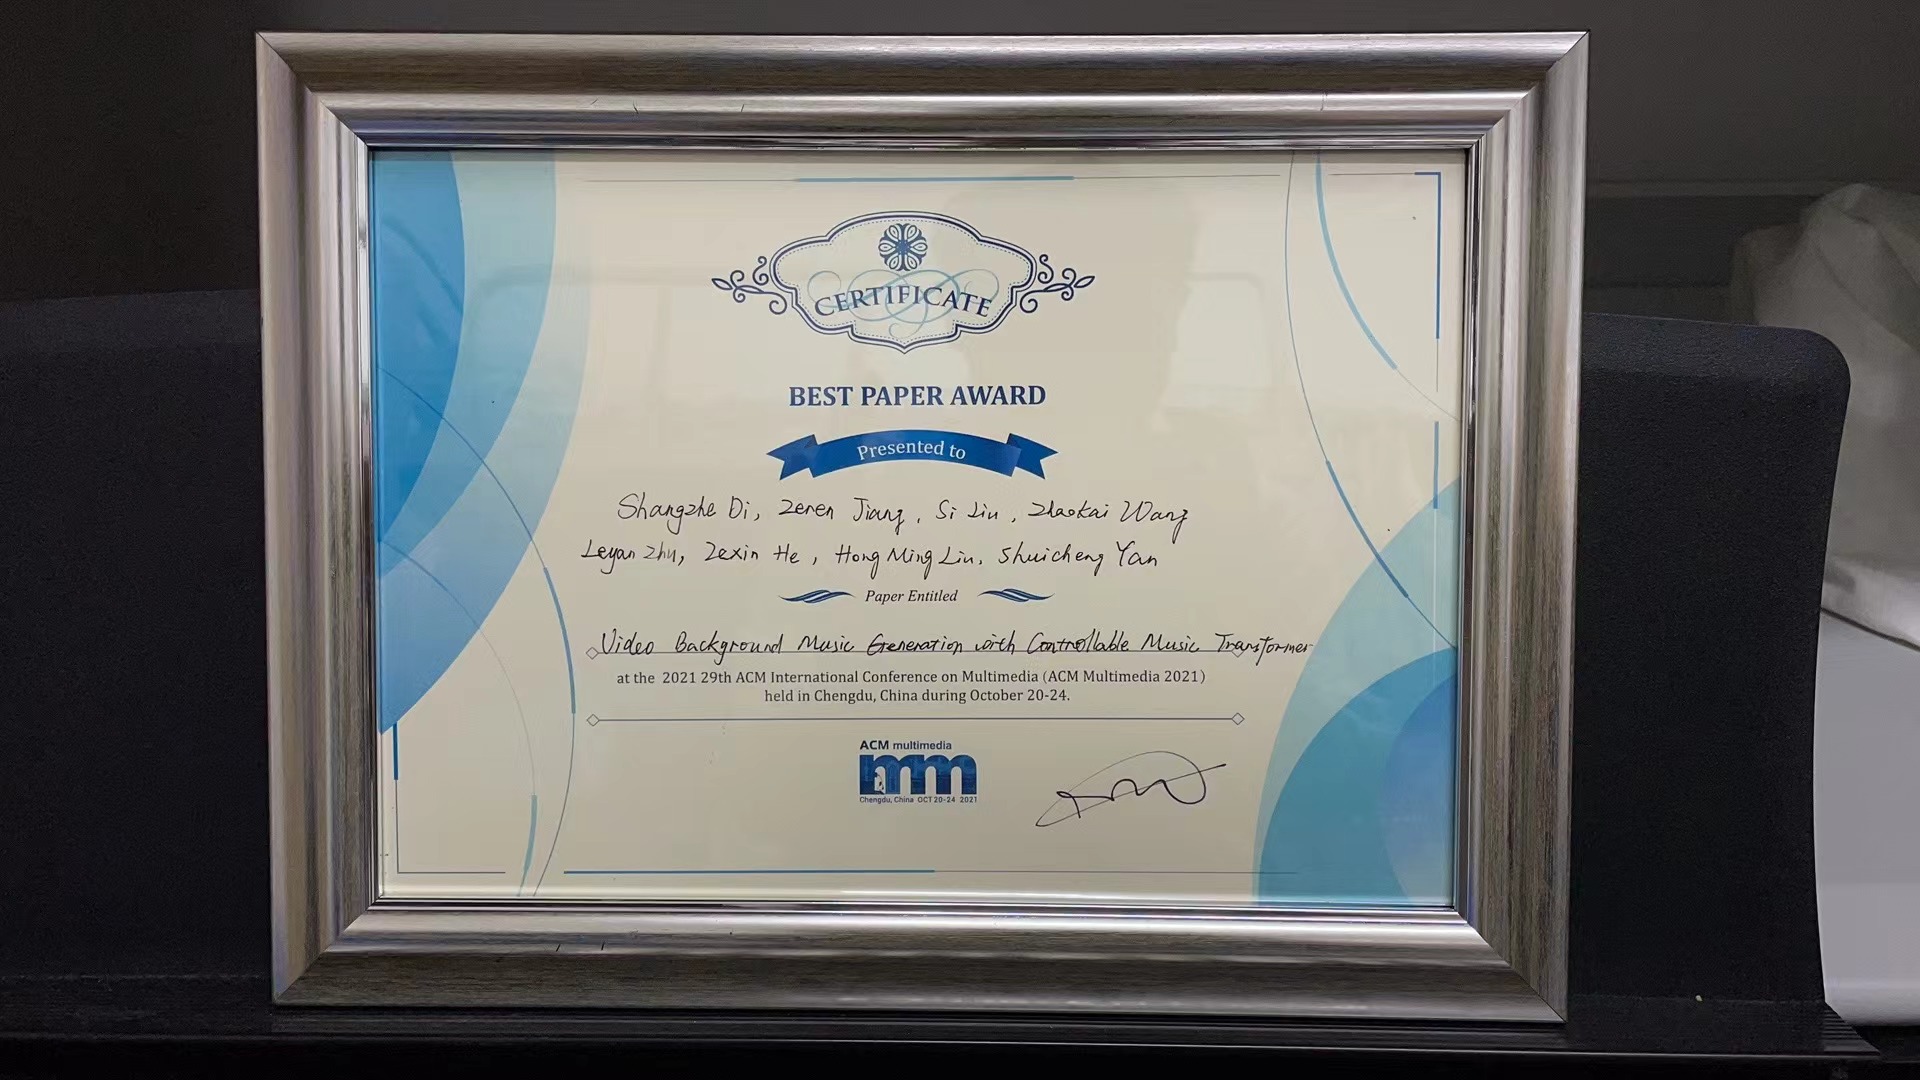
- Best Paper Award, ACM Multimedia2021
- Best Video Award, IJCAI Video Competition2021
- First Prize Scholarship ×2 (top 10%), Beihang University2019, 2021
- Full Scholarship for Exchange Program, China Scholarship Council2019
- Special Prize Scholarship (top 3%), Beihang University2018
Academic Service
Reviewer of CVPR, ICCV, ECCV, ICLR, NeurIPS, and ICML.